The variants are built, the plate is read, and none outperforms the parent. The natural reaction is to generate another mutation list. Before doing that, determine what the first screen actually ruled out.
A failed screen can mean no tested variant improved the endpoint, the assay could not resolve improvements, or the experimental pipeline prevented useful comparison. Those outcomes require different next rounds. More candidates help only after you know which problem you are trying to solve.
The aim is to turn an expensive disappointment into a smaller set of explicit hypotheses, then select experiments that can distinguish them.
Key takeaways
- Separate valid negative results from missing samples, censored values, and failed measurements.
- Audit assay resolution and preparation variability before accepting the top-ranked variant.
- Give each follow-up experiment an explicit purpose: confirmation, explanation, or a distinct alternative hypothesis.
Define the failure before diagnosing it
Return to the original objective. Was success higher activity, better expression, improved thermal behavior, longer storage life, or a combination? Did the assay directly measure that property, or only a convenient proxy?
An apparent thermal transition, for example, may not capture the handling stability needed for a binding experiment. A fluorescence signal may combine expression, reporter maturation, and sample recovery. A variant can improve one component while worsening another.
Write a precise statement such as “no variant exceeded the parental activity-retention criterion under this incubation protocol.” Avoid broader conclusions such as “the designs do not work” unless the evidence supports them.
Our discussion of thermal-shift readouts and practical stability illustrates why the endpoint needs to remain explicit.
Audit the assay before interpreting the ranking
Inspect raw data, blanks, positive and negative controls where available, parental replicates, and plate layout. Check whether the parent behaved as expected and whether the assay had enough dynamic range to detect a useful change.
Look for edge effects, timing differences, saturation, background subtraction problems, and batch structure. If every variant of one design class occupies the same plate region or expression batch, a systematic experimental effect may be confounded with the design strategy.
Technical replication estimates one part of variability. An independent expression or purification can reveal additional variation that repeated readings from the same preparation will miss. Choose the level of replication based on the uncertainty affecting your decision.
When the controls fail, repair the assay and repeat an informative subset before treating the variant labels as trustworthy training data. A model cannot reliably learn the intended phenotype from measurements dominated by an unrelated procedural failure.
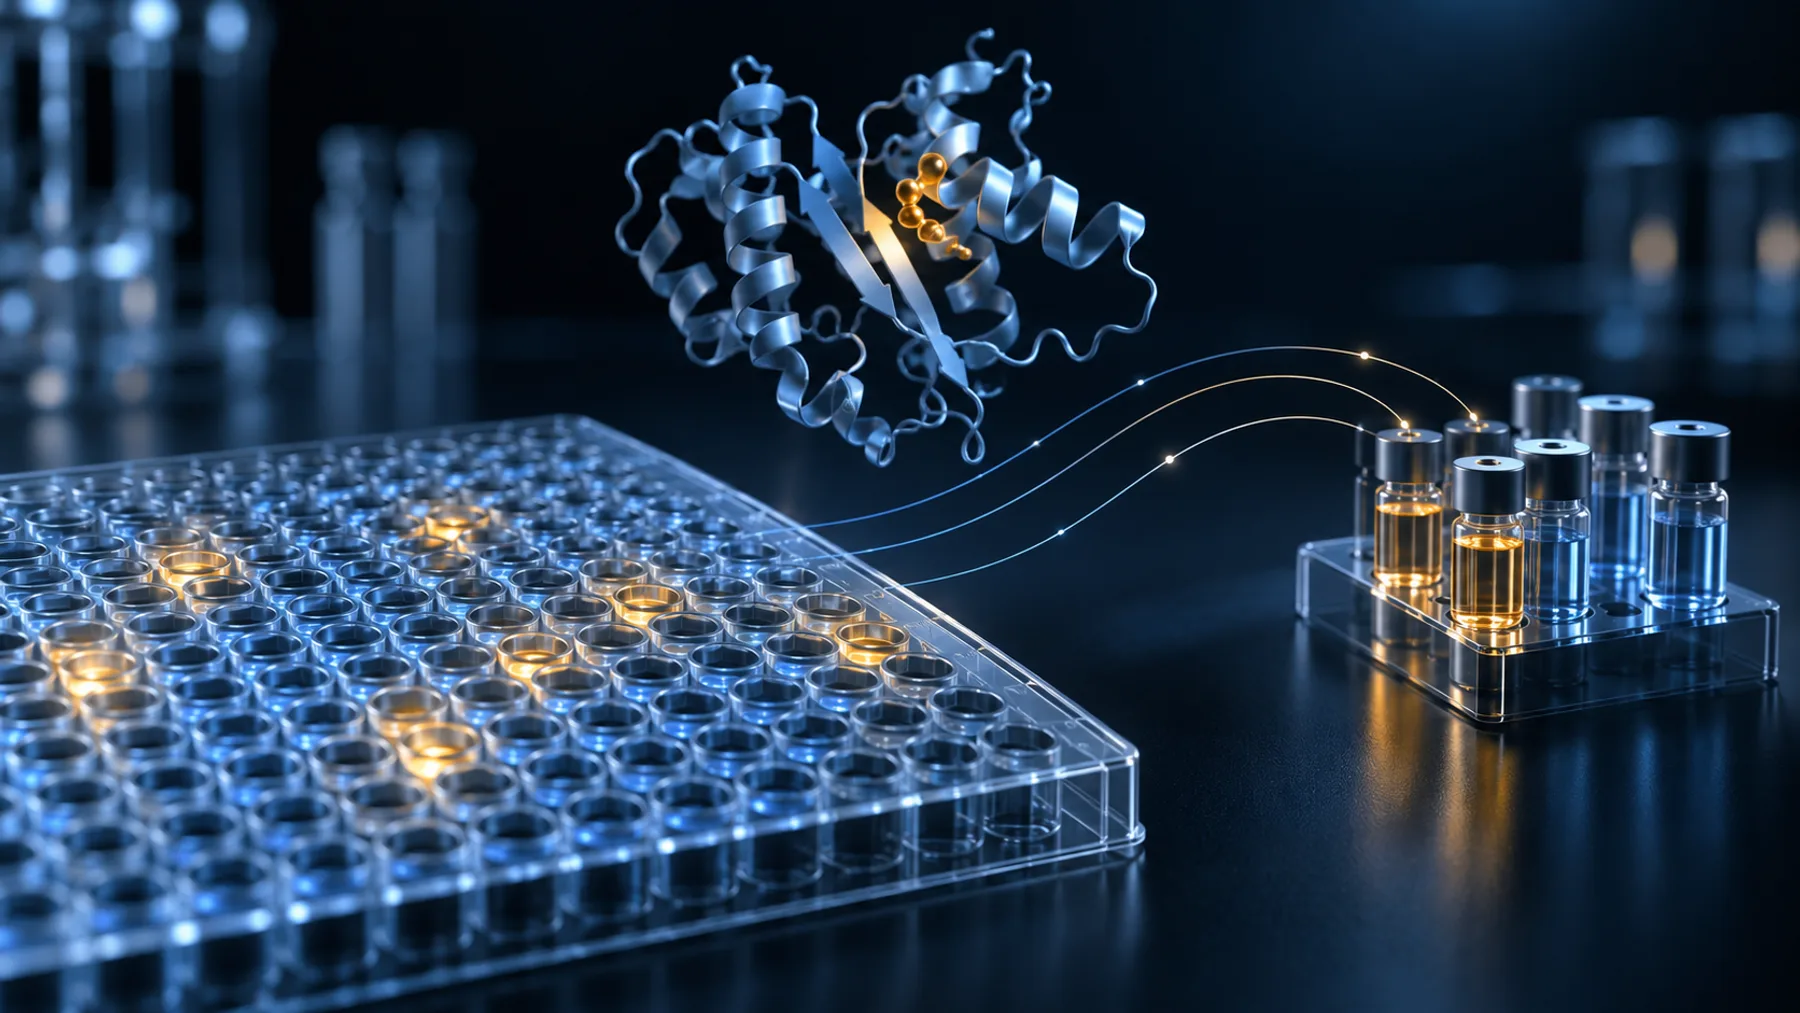
Figure 1. Before interpreting a screen, examine controls, measurement range and missing samples. The plate is conceptual and does not display experimental results.
Distinguish a measurable improvement from an attractive ranking
Every finite screen has a top-ranked sample, even if all variants have the same underlying performance. Choosing the highest observed value selects partly for biological effect and partly for favorable measurement noise. The question is whether the apparent advantage persists when it is measured again under a comparison that can resolve the effect size that matters.
Separate three quantities: the difference you observed, the variation in the measurement, and the minimum improvement worth pursuing. A small repeatable change may be statistically distinguishable yet commercially irrelevant. A potentially useful change may remain unresolved because the experiment is too variable. Neither situation is captured by reporting only a rank or a percentage relative to one parental well.
Assay-quality statistics can help where their assumptions fit. Zhang, Chung and Oldenburg (1999) introduced the Z-factor framework to consider signal separation and variability together in screening. A well-separated positive and negative control does not, however, guarantee enough resolution to distinguish a small improvement over the parent. Evaluate the part of the response range in which the engineering decision occurs.
If parental values vary substantially across preparations, repeating plate reads from one preparation understates the uncertainty relevant to a future production run. If preparation is reproducible but plate position matters, independent production alone may not remove that bias. Match confirmation to the observed source of variation rather than using “triplicate” as a complete description of replication.
Before selecting more candidates, write down the comparison that would change the decision. For example: would a repeated advantage of the observed size justify further characterization, or does the project require a larger improvement? This prevents the second round from becoming a search for any favorable-looking difference after the original objective has been missed.
Locate the failure in the experimental pipeline
| Observation | What to investigate next |
|---|---|
| Little or no target expression | Sequence verification, construct architecture, host and expression conditions |
| Expression but poor soluble recovery | Folding, extraction, aggregation, and formulation |
| Purified material but inconsistent assay values | Concentration normalization, identity, handling, and assay precision |
| Reproducible loss of function | Whether the design changed essential structural or functional constraints |
| Reproducible neutral variants | Candidate diversity, endpoint sensitivity, and the original design hypothesis |
Keep these outcomes separate. A variant that never produced enough target for measurement does not have a measured activity of zero. A sample that failed concentration normalization does not establish a sequence-specific defect in catalytic performance.
If many constructs fail at the same upstream step, changing the mutation-ranking model may have little effect. Review the common construct and experimental context. Our construct-boundary troubleshooting guide offers a starting point for that investigation.
Preserve negative, missing, and censored results differently
A useful results table includes the exact sequence, parental reference, batch, preparation, assay conditions, raw and processed values, uncertainty, and a measurement-status field.
Use separate statuses for a valid measured result, no target obtained, an assay failure, a value below the quantification limit, and an experiment not performed. A value below a limit is bounded information; it is not necessarily numerical zero. An unmeasured sample should not silently become a negative example.
Record exclusion reasons before looking for a preferred conclusion. If a sample is removed from analysis because of a documented assay fault, retain its raw data and the reason. This preserves the distinction between experimental quality control and selective reporting.
Our article on calibration and protein-stability predictions explains why endpoint and data quality matter when using experimental feedback.
Identify what the first round actually tested
Review the candidate set as a group. Were most mutations near the same site? Did they rely on the same structural assumption? Were they all chosen by one score with similar sequence changes? Ten variants can represent far fewer than ten independent ideas.
Separate an unsuccessful hypothesis from an insufficient test. If a proposed packing improvement repeatedly harms function in well-measured variants, revisit the local mechanism. If the candidates were nearly indistinguishable and the assay was noisy, the experiment may not resolve whether the broader idea is useful.
Also inspect numbering, construct identity, and pre-existing mutations. A correct structural proposal mapped to the wrong expression sequence can invalidate the entire round. Verify representative plasmids or sequence records before interpreting a surprising shared pattern.
Worked example: twenty-four designs, several different failures
Suppose a hypothetical screen contains 24 designed variants. Eight do not yield enough target for the intended assay. Four have failed measurement controls. Ten produce valid measurements comparable to the parent within the experiment's resolution. Two show an apparent gain in the first preparation. Describing the round as “22 failures and two hits” would erase the most useful distinctions.
| Group | What the result establishes | What it leaves unresolved |
|---|---|---|
| Eight with insufficient target | The production path did not deliver an assayable sample | Their activity or stability at comparable target concentration |
| Four with failed controls | The measurements cannot support the intended comparison | The variants' underlying performance |
| Ten with valid neutral results | No improvement was resolved under the tested conditions | Smaller effects or performance under a different endpoint |
| Two with an apparent gain | Candidates for confirmation exist | Reproducibility and retained secondary properties |
The appropriate next round depends on which group dominates the project's uncertainty. If the eight production failures share a construct feature, a focused construct question may be more informative than another ranking model. If the four assay failures cluster by plate position, review the measurement process. If the ten neutral results span genuinely different hypotheses, the evidence against a large easy improvement is stronger than if they all repeat the same idea.
The two apparent gains should not immediately become the only positive labels in a training set. Confirm their identity, the normalization, and the result at the level of preparation that matters. Also retain the parent and relevant negative or neutral comparators. A confirmation round that measures only the winners cannot reveal whether the whole assay has shifted upward.
This is an example of allocating experiments by information value. A repeat can resolve whether a lead exists. A deliberately different candidate can resolve whether the first design rationale was too narrow. An upstream check can establish whether the original variants were ever fairly tested. These are different uses of the same limited budget, and the record should say which uncertainty each allocation addresses.
Divide the next round by purpose
Choose a budget that matches the project, then allocate candidates to three useful roles:
- Reproducibility checks: the parent, relevant controls, and selected variants whose results need confirmation.
- Local follow-up: changes that test a specific explanation for the strongest or most informative first-round result.
- Alternative hypotheses: candidates that differ meaningfully in site, mechanism, or design rationale.
The allocation is project specific. A hypothetical twelve-variant budget might reserve four positions for checks, four for local follow-up, and four for alternatives. That is an illustration of transparent planning, not an optimal universal ratio. If the assay itself failed, most of the next budget may properly go to repairing and validating measurement.
Figure 2. A follow-up round should have explicit purposes: confirm the evidence, examine a specific explanation and test an alternative. The sample arrangement is illustrative, not a prescribed allocation.
Use machine learning only where the data support it
Small-data methods can help prioritize protein variants. Biswas and colleagues' Low-N protein-engineering study demonstrates a data-efficient approach in tested systems, and machine-learning-assisted evolution with combinatorial libraries provides another experimental framework.
These studies do not imply that any small failed screen is enough to train a reliable project-specific predictor. Evaluate label quality, diversity, batch effects, and how far proposed candidates lie from measured sequences. With very few independent observations, performance estimates can be unstable.
Keep prospective candidates separate from data used to choose or tune the method. When possible, compare model-guided selection against a meaningful baseline under the same experimental conditions. Report what was actually tested rather than presenting retrospective agreement as prospective validation.
For candidate prioritization in Orbion Stabilize or Orbion Design, retain the prediction and measured result as separate records. Experimental feedback can inform a subsequent decision, but do not assume an automatic model update occurred unless that specific workflow has been configured and verified.
Evaluate a model against the next decision it must make
A random train/test split can be overly optimistic if nearly identical variants, repeated readings of the same sample, or the same preparation batch appear on both sides. The model may benefit from information that would not be available when selecting a genuinely new candidate. Choose an evaluation split that reflects the intended use: a new preparation, a different combination of changes, or a more distant sequence background are different tests.
Do not count technical replicates as independent sequences. Preserve them for estimating measurement variability, then keep the relationship between sequence and preparation explicit. Similarly, distinguish measured neutral outcomes from missing targets and failed assays. A sophisticated model trained on incorrectly collapsed labels can produce a precise ranking of the wrong problem.
The published study by Wu et al. (2019) offers an experimental example of using learning to guide combinatorial exploration. Its published correction should accompany detailed reuse of the reported variant tables. The broader lesson is to evaluate prospective selection in a defined experimental system, rather than treating model-assisted design as a guarantee of success on any small dataset.
A meaningful baseline helps separate model value from an easier explanation. Depending on the project, that baseline might be a simple ranking rule, a diversity-based selection, or the existing design process. Compare them under the same measurement and budget constraints. Retrospective agreement with data used to choose the model is useful for development, but it is not independent evidence that the model will improve the next screen.
With very little reliable data, the most useful output may be a set of testable hypotheses rather than a fitted predictor. Document where the model is extrapolating, what measurements could challenge its ranking, and which tradeoffs are outside its training endpoint. That makes the next round informative even if the final selection remains partly based on scientific judgment.
Keep a stopping rule for each hypothesis. Repeated well-measured neutral results may justify reducing effort on one design rationale. A reproducible benefit may justify more detailed characterization. A control failure justifies repairing the measurement. Changing course for one of these reasons is a result of the screen, not evidence that the experiment had no value.
Decide in advance what will change your mind
Write the success criterion, acceptable uncertainty, and next decision before running round two. Define what would justify combining mutations, changing the assay, revising the construct, or stopping a particular design hypothesis.
For a hypothetical enzyme screen, a modest gain that repeats across independent preparations while preserving initial activity may be more useful than a large one-off signal. For a membrane receptor, retained function and monodisperse recovery may constrain which apparent stability improvements are worth pursuing.
The first screen has value when it changes the next experiment. A clear record of why variants failed, which measurements are trustworthy, and which hypotheses remain open makes the next round more informative even when it does not immediately produce a winner.
Common questions
Should I discard all failed variants from the dataset?
No. Preserve valid negative measurements. Separate them from missing or uninterpretable outcomes, and retain the reasons for each status.
Should I build more variants or repeat the best ones?
Repeat when measurement uncertainty could change the decision. Expand when the assay is reliable and the remaining uncertainty concerns sequence space or design hypotheses. Many projects need some of each.
Does a failed round mean the prediction method is useless?
Not necessarily. First verify that the experiment measured the intended endpoint and that the tested candidates fairly represented the hypothesis. Then assess the method against the evidence rather than its promise.
References
- Zhang JH, Chung TD, Oldenburg KR. A simple statistical parameter for use in evaluation and validation of high throughput screening assays. Journal of Biomolecular Screening. 1999. doi:10.1177/108705719900400206
- Biswas S, et al. Low-N protein engineering with data-efficient deep learning. Nature Methods. 2021. doi:10.1038/s41592-021-01100-y
- Wu Z, et al. Machine learning-assisted directed protein evolution with combinatorial libraries. PNAS. 2019. doi:10.1073/pnas.1901979116. See also the published correction to variant tables.